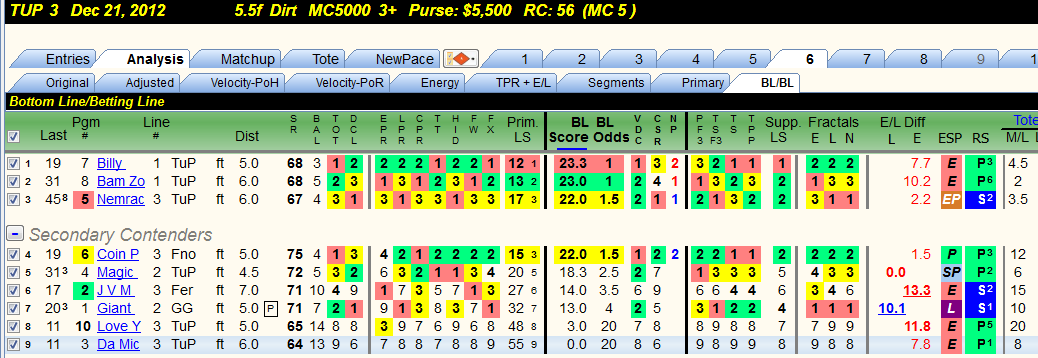
With respect, it's ridiculous to compare relative value of different tools and methods on the basis of a single race, much less a low class Maiden Claiming race like this one. Even weaker to borrow numbers from one method and adjust them by a different method. Each method may have its own well functioning, built in and coherent adjustment system - and each would likely be rendered less effective -
over a large number of events - by mixing and matching numbers from one into the other. Just my opinion - and advice to others, FWIW.
It is meaningless to base any comparison between methods on 1 race.
Also FWIW, here is how the race would likely have been done by almost anybody using RDSS, who has been following any of the discussions here about paceline selection and Contender identification. A different outcome than your mash-up above: